Padwan Proxy
Padwan Proxy serves the Anthropic Messages API (/v1/messages and /v1/messages/count_tokens)
on top of any OpenAI-compatible backend, so Anthropic clients such as Claude Code can use it.
It is built on padwan-ai's Anthropic↔OpenAI
translation layer and served by granian (RSGI)
via gravier.
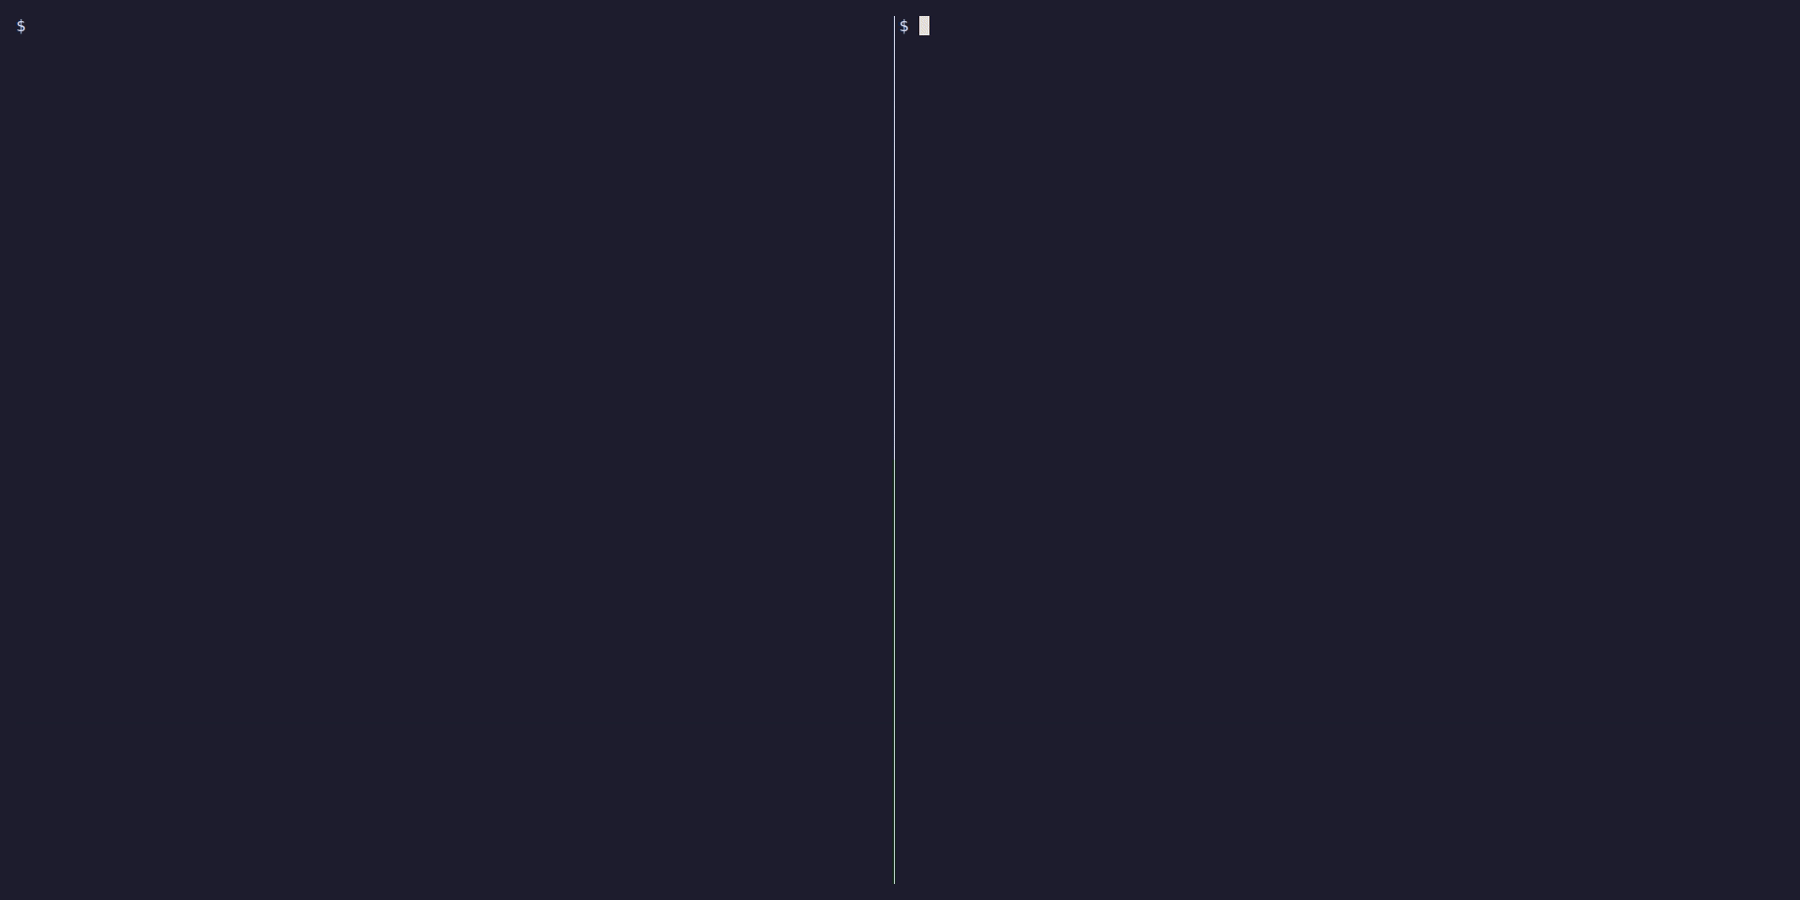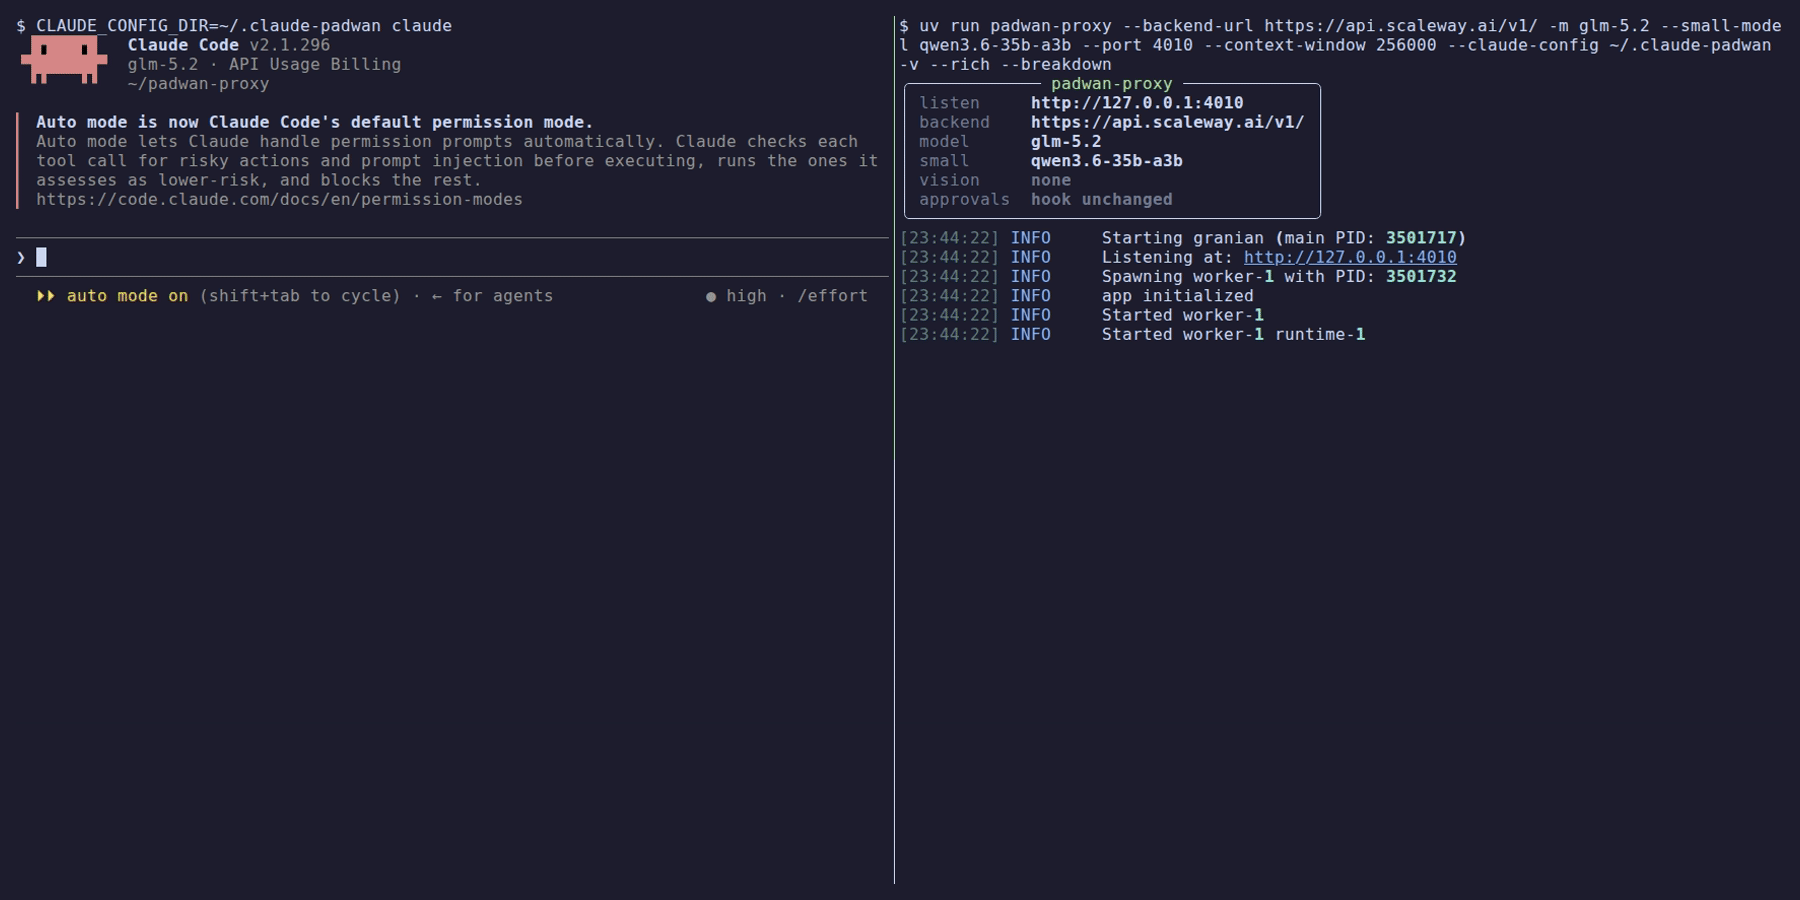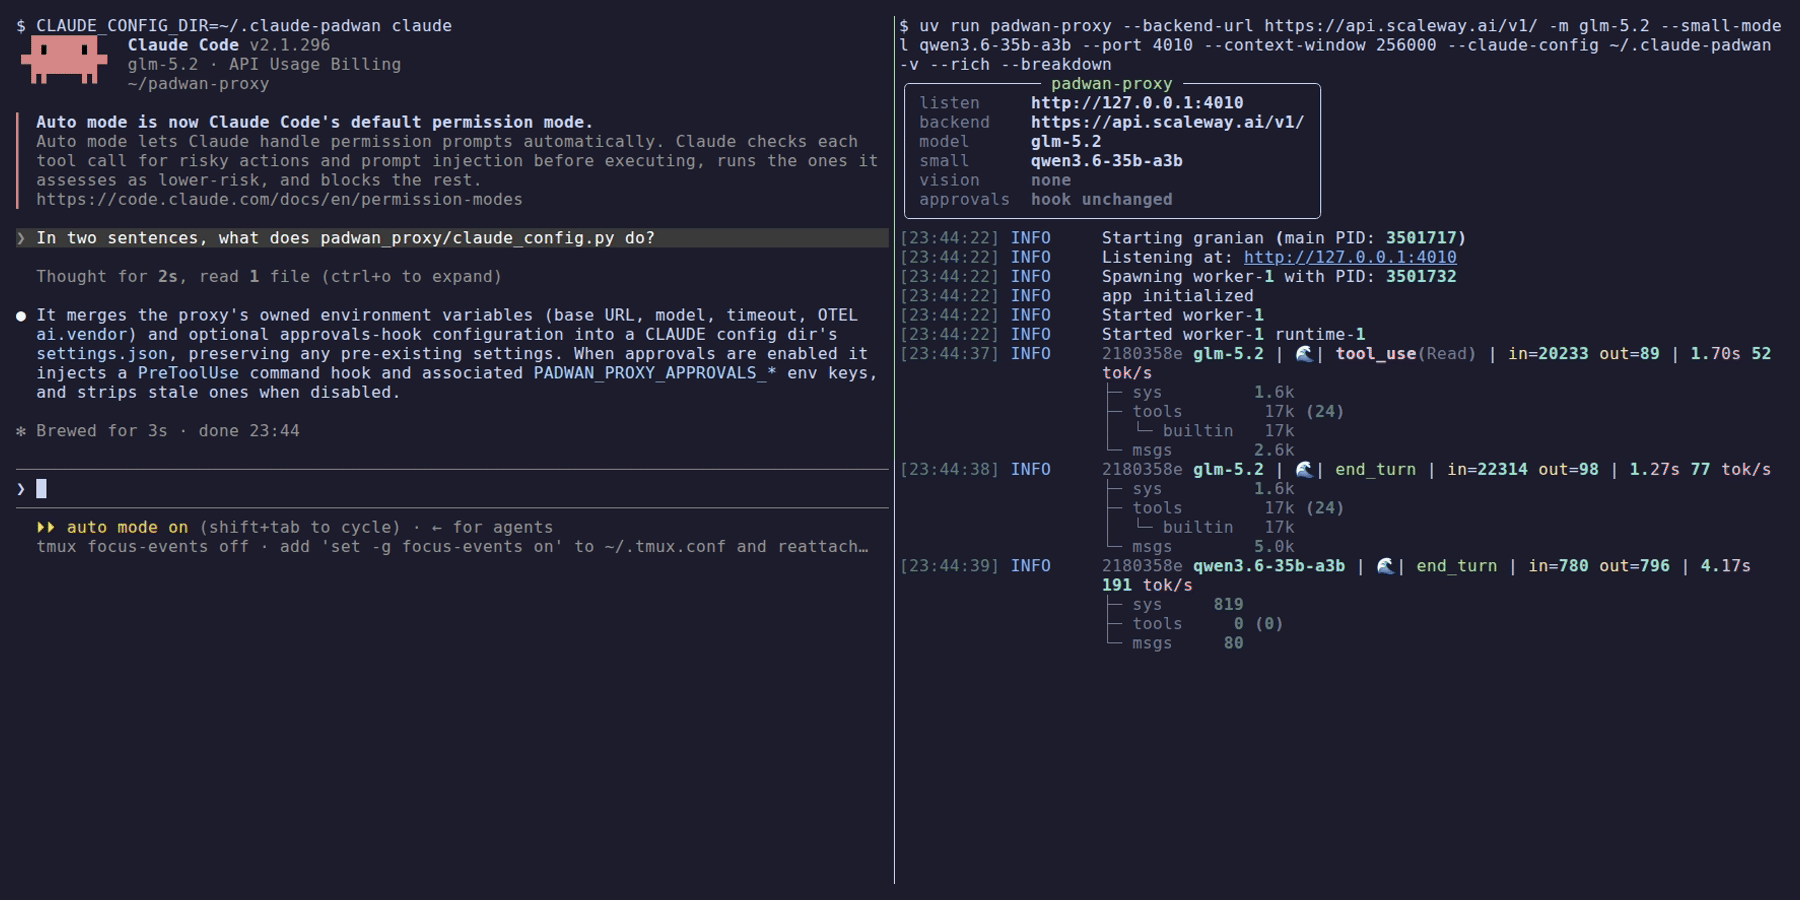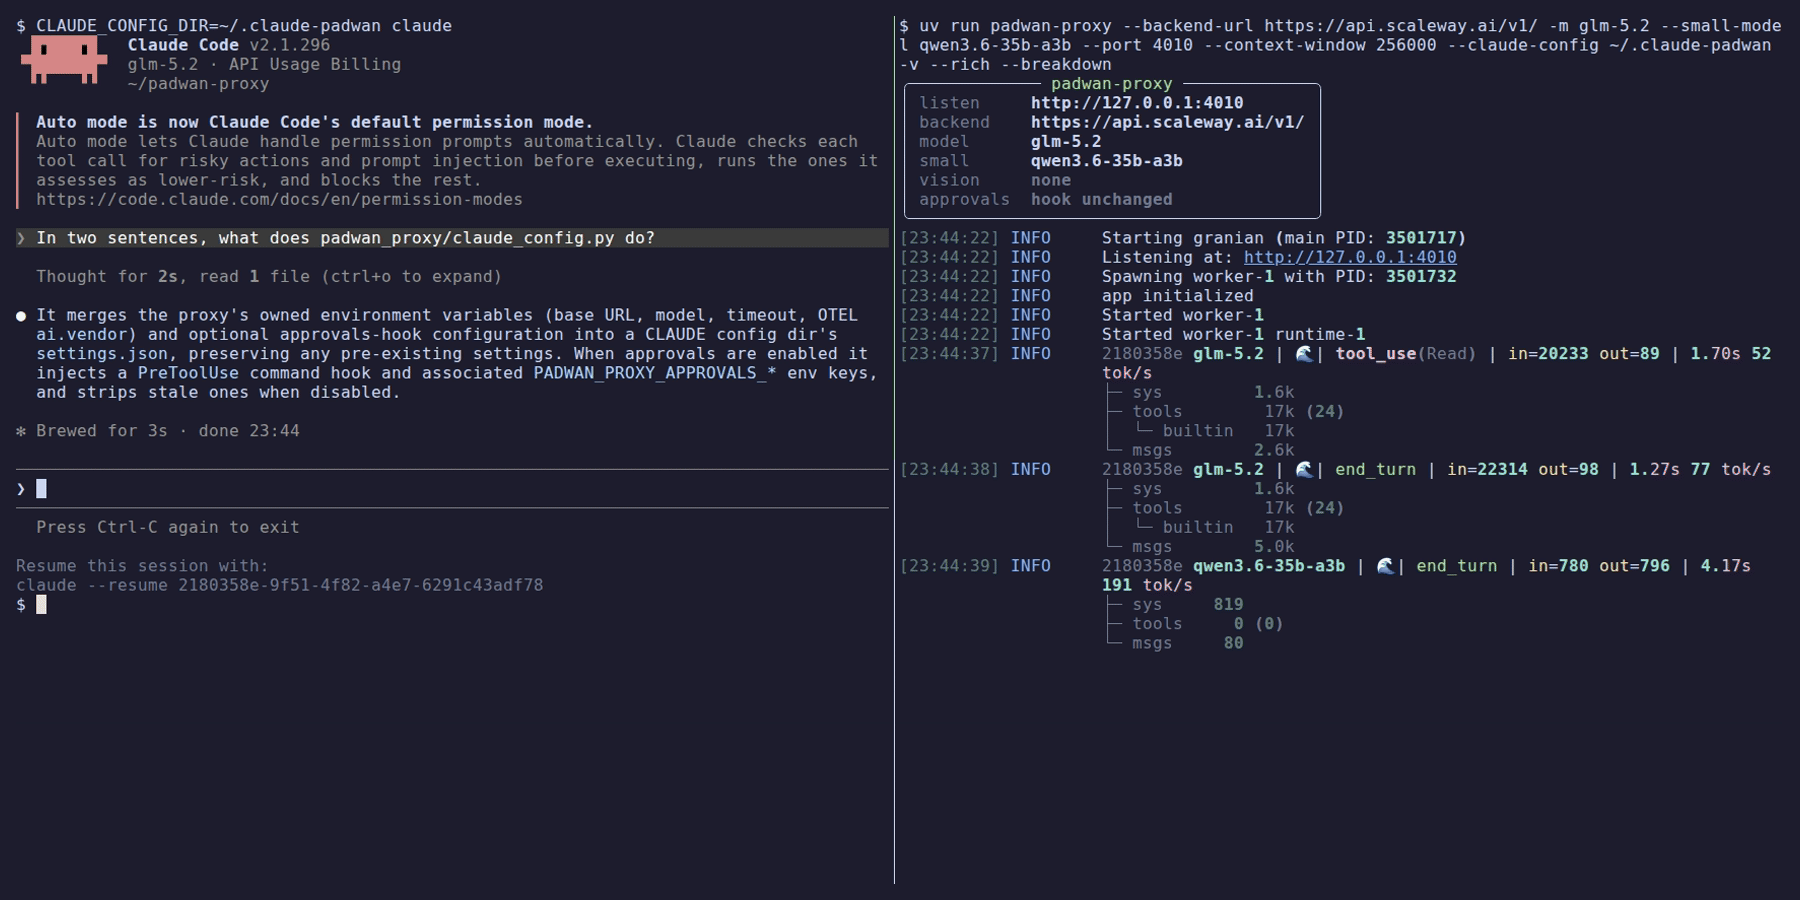
Prerequisites: Python 3.13+ with uv, and an API key for an OpenAI-compatible backend that supports function calling.
Quickstart
-
Export the backend key:
-
Start the proxy:
uvx padwan-proxy --backend-url https://api.example.com/v1/ \
  -m my-model --small-model my-small-model
Or with Docker:
-
Point the client at it:
Claude Code now answers with my-model. To keep model names in one place, let the proxy
write the client config instead — see Claude Code.
Limitations
- The proxy does not translate Anthropic thinking budgets; reasoning must be enabled on the backend. Models that hide their reasoning emit no thinking blocks.
count_tokensis an estimate (request size / 4), not a backend tokenizer count.- The backend context window cannot be discovered; pass it with
--context-window.